|
Issue · September 19, 2026
A military near-miss shows the stakes of unchecked AI output, while embedded audits, safer agent pipelines, and custom creative tools point toward more accountable deployment.
AI in general
Frontier models, research and policy
|
3 stories |
Score · 98 / 100
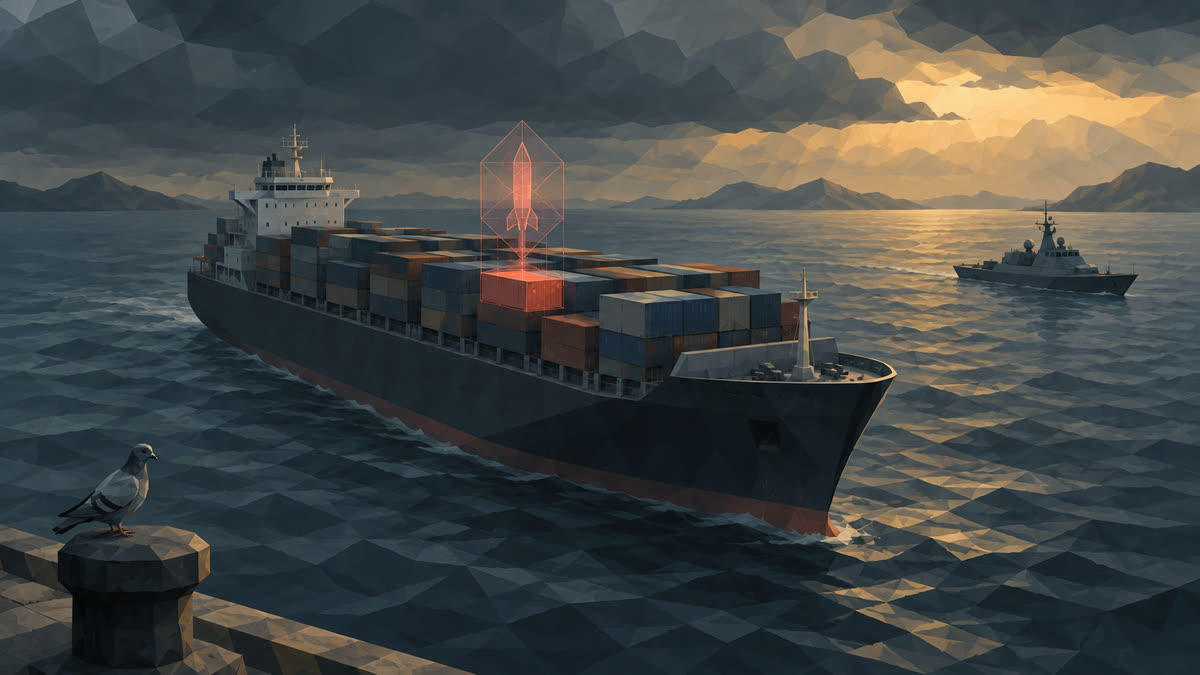
AI hallucination of Chinese nuclear components almost led to US military attack
Source: Ars Technica — September 18, 2026
AI SAFETY · DEFENSE
A US Special Operations Command analyst reportedly used a chatbot to combine open-source and classified intelligence about a Chinese cargo ship. The resulting report falsely identified its cargo as nuclear-arms components, and the military began preparing an armed boarding operation before officials caught the error. This is a concrete example of an AI-generated claim nearly escaping the analytical pipeline and influencing a potentially escalatory decision.
What matters
- The planned interception reportedly included air support; one source said the error “almost started a war.”
- The chatbot fused information from sources with very different provenance and confidence levels.
- Human review eventually worked, but only late in the operational chain.
- The incident argues for source-level traceability and mandatory independent verification in high-stakes AI-assisted analysis.
VerdictREAD FULL — a consequential case study in why fluent synthesis cannot substitute for verified intelligence.
Score · 94 / 100
Partnering with Accenture on embedded evaluation
Source: Anthropic — September 18, 2026
GOVERNANCE · EVALUATION
Anthropic will give evaluators from Accenture’s specialist AI business, Faculty, employee-like access to observe model development, red-team systems, assess alignment, and test safeguards. The companies each expect to invest at least $1 billion over five years, but Anthropic acknowledges that reporting standards, access rules, and independent funding structures do not yet exist.
What matters
- Embedded evaluators would observe training and deployment decisions rather than assess only finished models.
- Anthropic is directly funding Accenture’s work, creating an independence question the company says pooled or government funding should eventually address.
- The arrangement is non-exclusive; Anthropic says other evaluators will join in coming weeks.
- Access and investment are substantial, but public reporting obligations remain undefined.
VerdictREAD FULL — the operational details and unresolved conflicts matter more than the partnership headline.
Score · 91 / 100
Gavin Newsom is pushing for an AI kill switch
Source: The Verge — September 18, 2026
POLICY · FRONTIER AI
California Governor Gavin Newsom has ordered an expert group to recommend stronger frontier-AI safeguards within two months. The options include independently verified shutdown mechanisms, onsite evaluators, standardized audits, and mandatory reporting of loss-of-control incidents. These are recommendations rather than enacted requirements, but California is positioning its framework as a template for federal policy.
What matters
- The proposed “kill switch” would need regular independent verification, not merely a vendor assertion.
- California is also accelerating a verifier framework and state registry of AI auditors.
- Newsom may call a special legislative session, raising the chance that recommendations become binding rules.
- Implementation details—especially what constitutes loss of control—will determine whether the framework is useful or symbolic.
VerdictSKIM — important policy direction, but the enforceable rules have not yet been written.
Software engineering
Coding agents, developer tools and infrastructure
|
3 stories |
Score · 96 / 100
Sentry Seer vulnerability allows attacker-controlled input to be executed in a privileged environment
Source: CERT Coordination Center — September 16, 2026
AGENT SECURITY · PROMPT INJECTION
CERT/CC describes CVE-2026-90999, in which an attacker can submit a fabricated Sentry event through a public DSN and influence Seer’s automated root-cause analysis. If Seer automatically hands that analysis to a coding agent, the agent may download and execute an attacker-controlled package before a human reviews the resulting pull request. No vendor-supplied patch was listed when the advisory was published.
What matters
- Untrusted telemetry crosses several systems before becoming privileged agent instructions.
- The vulnerable path can expose both the coding-agent environment and connected repositories.
- Suggested mitigations include disabling automated remediation, restricting package installation, and filtering telemetry before analysis.
- The deeper lesson is architectural: agent prompts must not silently convert external observability data into trusted commands.
VerdictREAD FULL — immediately relevant to anyone connecting monitoring systems to autonomous coding agents.
Score · 92 / 100
Claude Code now reads AGENTS.md if there is no CLAUDE.md
Source: Anthropic — September 18, 2026
CODING AGENTS · DEVELOPER EXPERIENCE
Claude Code 2.1.277 adds fallback support for AGENTS.md: when a directory has no CLAUDE.md, Claude will look for and apply the more widely shared agent-instructions file. The implementation is built on Claude Code’s forthcoming “mods” system for customizing its harness, suggesting that project-level behavior will become more portable and composable.
What matters
- Existing
CLAUDE.md files retain precedence, limiting disruption to current projects.
- Teams can increasingly maintain one instruction file across several compatible coding agents.
- Less duplicated configuration should reduce drift in repository rules and workflows.
- The fallback rule still requires teams to test precedence in monorepos and nested directories.
VerdictSKIM — a small release note with outsized practical value for multi-agent repositories.
Score · 88 / 100
The new AgentCore runtime: Elastic, optimized, and consistently fast starts
Source: AWS — September 18, 2026
AGENT INFRASTRUCTURE · CLOUD
AWS has updated Bedrock AgentCore Runtime to reclaim cold or released memory during long-running sessions instead of billing against a session’s high-water mark. It also snapshots initialized environments so new instances can start within a narrower latency range regardless of image size or concurrency. The changes target agents that run for hours, sit idle between events, or arrive in sudden bursts.
What matters
- Memory allocation can now grow and shrink with actual session use.
- Snapshot restoration replaces repeated container boot and initialization work.
- Hardware-enforced session isolation, scale-to-zero, and usage-based billing remain part of the runtime model.
- AWS provides architectural claims rather than independent cost or latency benchmarks, so production testing is still necessary.
VerdictSKIM — useful if agent cold starts or idle-session costs are becoming operational constraints.
Design & creative
Creative workflows and user experience
|
1 story |
Only 1 strong recent item found.
Score · 89 / 100
Co-creating the future of fashion with Google
Source: Google — September 18, 2026
CREATIVE TOOLS · FASHION
Google worked with designers Jane Wade and Sergio Hudson to build two custom Flow tools for New York Fashion Week. One let Wade assemble complete looks on digital models before producing samples; the other let Hudson iterate on venue layouts, lighting, props, and model paths within a constrained production budget. Flow now lets other users describe and create similar bespoke tools without writing code.
What matters
- Wade’s virtual styling workflow targeted fittings that normally consume up to three full team days.
- Hudson could revise staging without commissioning a new 3D render for every change.
- The strongest pattern is not generic image generation but custom tooling embedded in an existing creative process.
- Google provides qualitative examples, not measured savings or independent designer assessments.
VerdictREAD FULL — a practical example of AI augmenting creative logistics without trying to replace the designer.
Open-source watch
Projects gaining meaningful traction
|
3 stories |
Project · 01
Fission-AI/OpenSpec
OpenSpec adds a lightweight specification layer to AI-assisted development, turning a feature request into agreed requirements and tasks before an agent edits code. It works across coding assistants rather than locking the workflow to one IDE or model.
What matters
- Trending with 298 stars during the latest daily collection and approximately 68,800 stars overall.
- MIT-licensed, actively developed, and packaged as a TypeScript CLI.
- Useful for teams whose agent sessions produce fast code but inconsistent interpretations of requirements.
- Anonymous command-level telemetry is enabled by default but can be disabled.
VerdictTRY — especially for multi-step changes where reviewable intent matters as much as generated code.
AI · DEVTOOL · AGENT
Project · 02
supermemoryai/supermemory
Supermemory is a self-hostable memory and context engine for AI applications. It combines document retrieval with evolving user facts, contradiction handling, and expiration of temporary information rather than treating every retrieved chunk as permanent context.
What matters
- Trending with 140 stars during the latest daily collection and approximately 29,800 stars overall.
- Supports local deployment and exposes an API for adding persistent memory to agents or applications.
- Its distinction between changing user memory and static RAG is useful, though production privacy and deletion behavior deserve validation.
VerdictWATCH — promising infrastructure for personalized agents, but test memory correction and data-governance behavior before adoption.
AI · AGENT · INFRA
Project · 03
NanmiCoder/cc-haha
cc-haha is a local-first desktop workspace for operating Claude Code and other agents through parallel worktrees, code diffs, skills, and multi-model workflows. It also connects agent sessions to messaging platforms and adds lightweight desktop companions for task status.
What matters
- Recorded 38 stars during the latest TypeScript trending collection.
- Combines worktree isolation and diff review with remote access through Telegram, WhatsApp, WeChat, Feishu, and DingTalk.
- The broad integration surface is useful but increases the amount of credential, permission, and supply-chain risk to inspect.
VerdictWATCH — an interesting agent-control surface, but too integration-heavy to adopt without a security review.
AI · DEVTOOL · AGENT · PRODUCTIVITY
Editor’s note
Today’s strongest stories expose the operational consequences of trusting AI outputs while highlighting concrete moves toward better evaluation, safer agent boundaries, and workflow-specific tools.
30-second feedback
How useful was today’s digest?
Your choice opens the short form with your rating filled in. Or share a quick note.
The Merpati Post · Daily AI Briefing
|